

🌍 Public RSVP
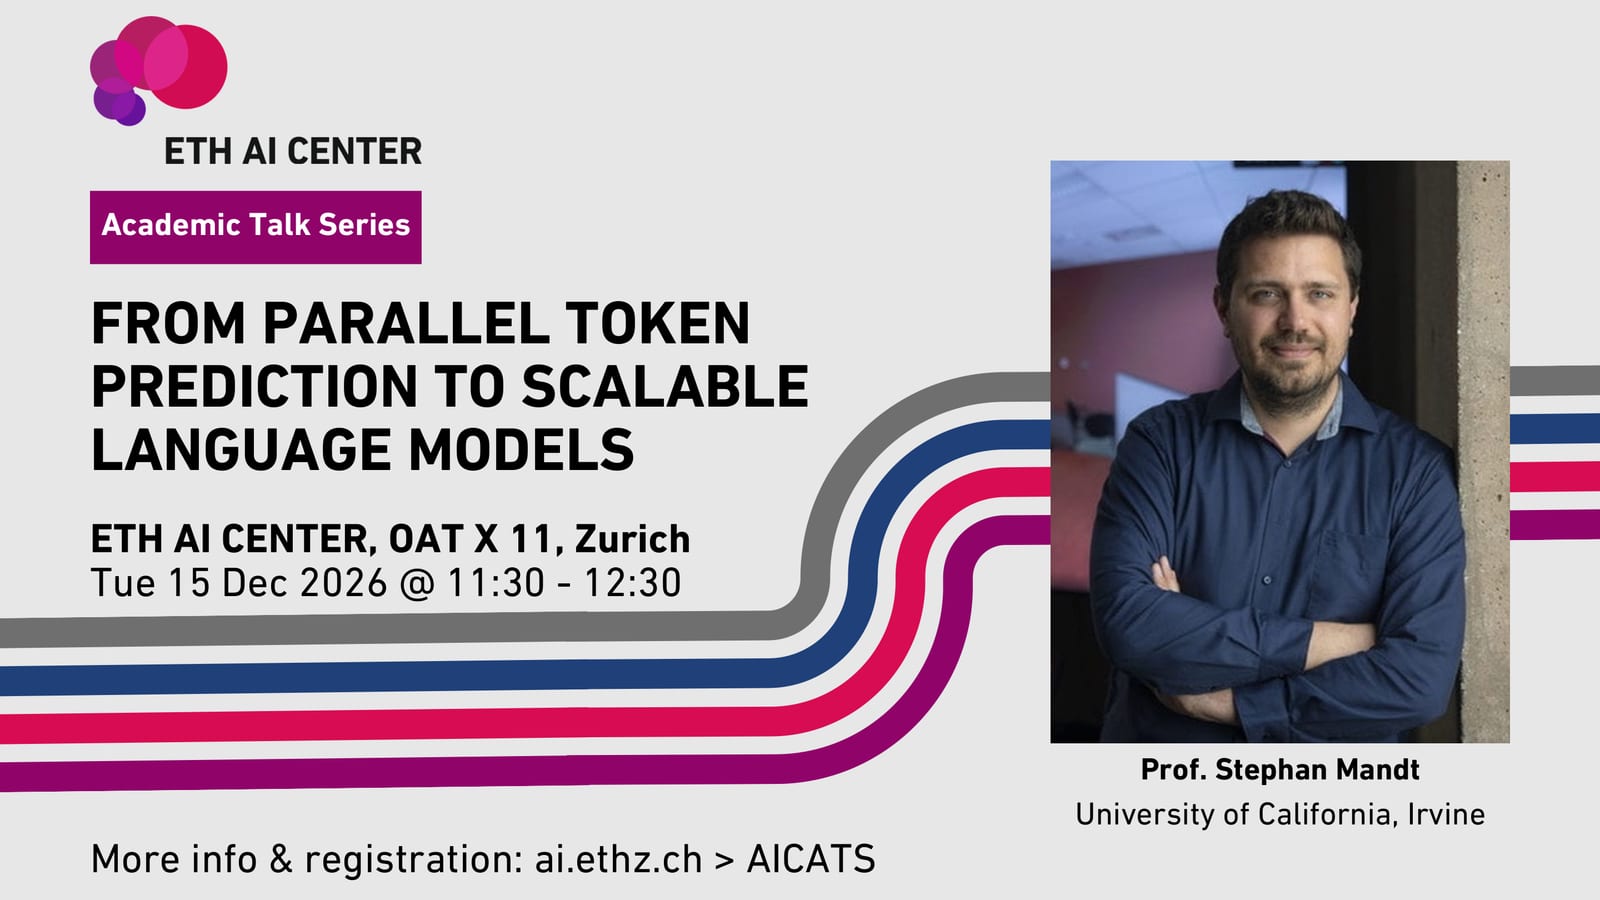
From Parallel Token Prediction to Scalable Language Models
When
Tuesday, 15 December 2026
12:30–13:30
“Interested” saves it to your list and sharpens your recommendations. “Going” marks your spot and opens the organizer’s page so you can grab the actual ticket.
Autoregressive language models generate text one token at a time, creating an inherent bottleneck that limits inference speed. Can we overcome this constraint without sacrificing generation quality? In this talk, I will present a line of work toward parallel language generation, progressing from Parallel Token Prediction (PTP) to Parallel Language Models (PLMs). Both approaches build on the insight that dependencies between tokens can be mediated through auxiliary random variables rather than sequential computation, enabling multiple mutually consistent tokens to be generated in a single forward pass. PTP establishes the theoretical foundations and explores distillation and inverse autoregressive training, while PLMs extend these ideas to end-to-end training through a variational objective. We demonstrate that PLMs can be pretrained at scales of up to 3 billion parameters while approaching autoregressive modeling quality. Interestingly, inference speedups follow a power law with model size, suggesting increasing benefits at larger scales. Our post-trained models match or exceed autoregressive performance on downstream tasks while achieving inference speedups of up to 5.7×, pointing toward a scalable alternative to sequential language generation.
Who's going
Speakers from
- Where
- OAT, Room 11, ETH AI Center Foyer, Zurich · More at ETH AI Center →
- Who's behind it
- ETH AI Center
- Who's going
- ~40 expected
- Registration
- 🌍 Open to all
More events like this
Same scene, around the same time.
Contracts signed in minutes — on your own domain
wesign.now — the European alternative to DocuSign and DocSend, in one Swiss tool. Free plan: 10 documents a month, no credit card.
Start for free