🌍 Public RSVP
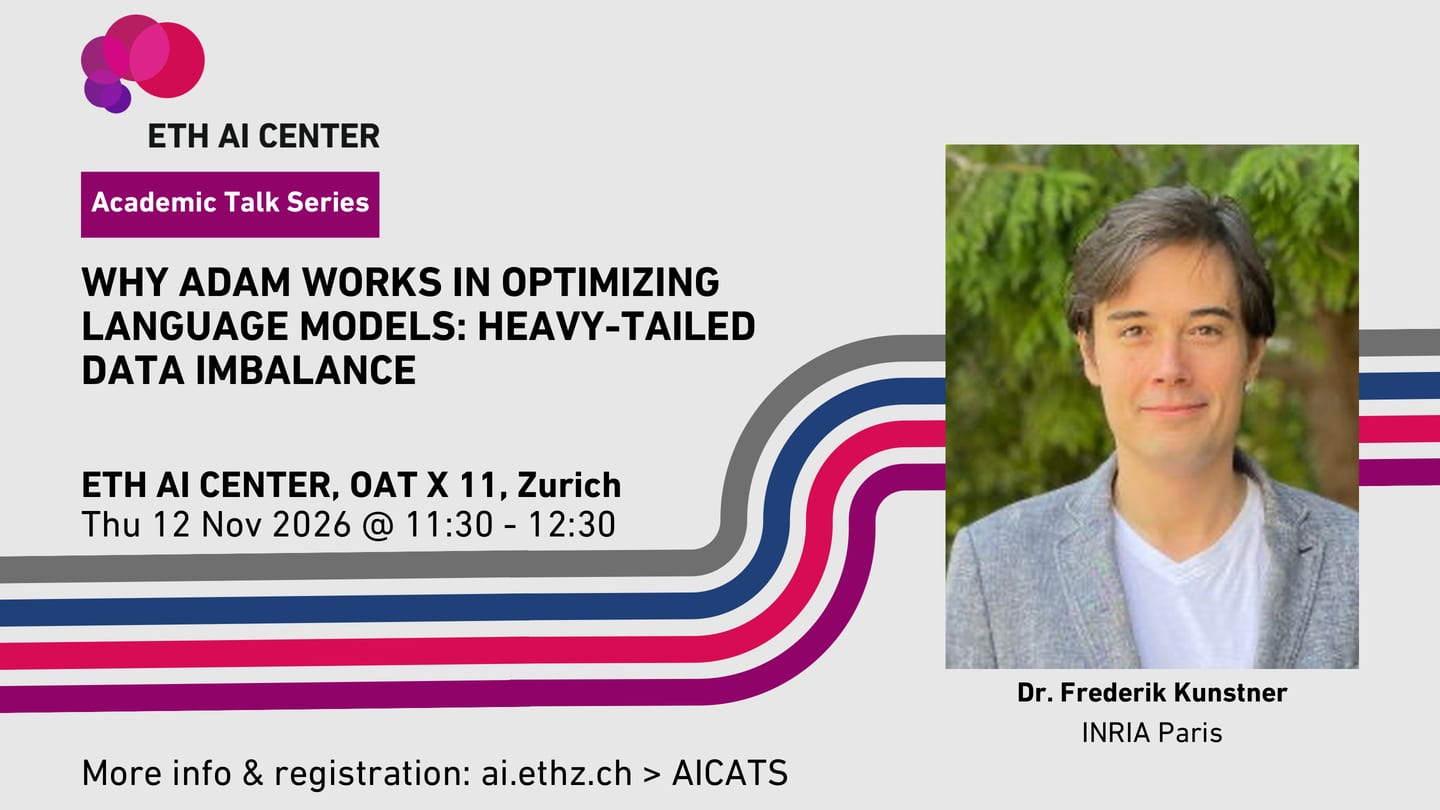
Why Adam work in optimizing language models: heavy-tailed data imbalance
When
Thursday, 12 November 2026
12:30–13:30
“Interested” saves it to your list and sharpens your recommendations. “Going” marks your spot and opens the organizer’s page so you can grab the actual ticket.
Adam and related methods are the default optimizers in training language models because gradient descent is so slow it is thought it simply does not work. Many methods have been proposed to improve on Adam, but we have a poor understanding of why it works better in the first place. This talk will be about understanding what makes language models hard for gradient descent, and how Adam fixes it. We give evidence that the problem is due to imbalance in the data: in language, some words are very frequent but the majority are rare, following Zipf’s law; the 𝑘th most frequent word has frequency proportional to 1/𝑘. This heavy-tailed imbalance leads to poor performance with gradient descent, while Adam and other sign-like methods do not suffer from the same slowdown. We show empirical evidence on language models, and prove a separation in the performance of gradient and a simplified form of Adam, sign descent, on a linear bigram model as we the vocabulary size grows.
Who's going
Speakers from
- Where
- OAT, Room 11, ETH AI Center Foyer, Zurich · More at ETH AI Center →
- Who's behind it
- ETH AI Center
- Who's going
- ~40 expected
- Registration
- 🌍 Open to all
More events like this
Same scene, around the same time.
Contracts signed in minutes — on your own domain
wesign.now — the European alternative to DocuSign and DocSend, in one Swiss tool. Free plan: 10 documents a month, no credit card.
Start for free